BetterRankings
ranking
causal-inference
python
sql
Off-policy evaluation of ranking policies from logged data alone, validated against 27M real impressions from a live A/B test.
Overview
Before shipping a new ranking policy, you want to know how it would perform. An online A/B test answers that, but it’s slow and costly. Off-policy evaluation estimates the answer from logs the current system already collected.
BetterRankings builds that pipeline and checks it against reality: 27M real impressions from ZOZOTOWN’s live A/B test (the Open Bandit Dataset), where the true click rates are known.
Results
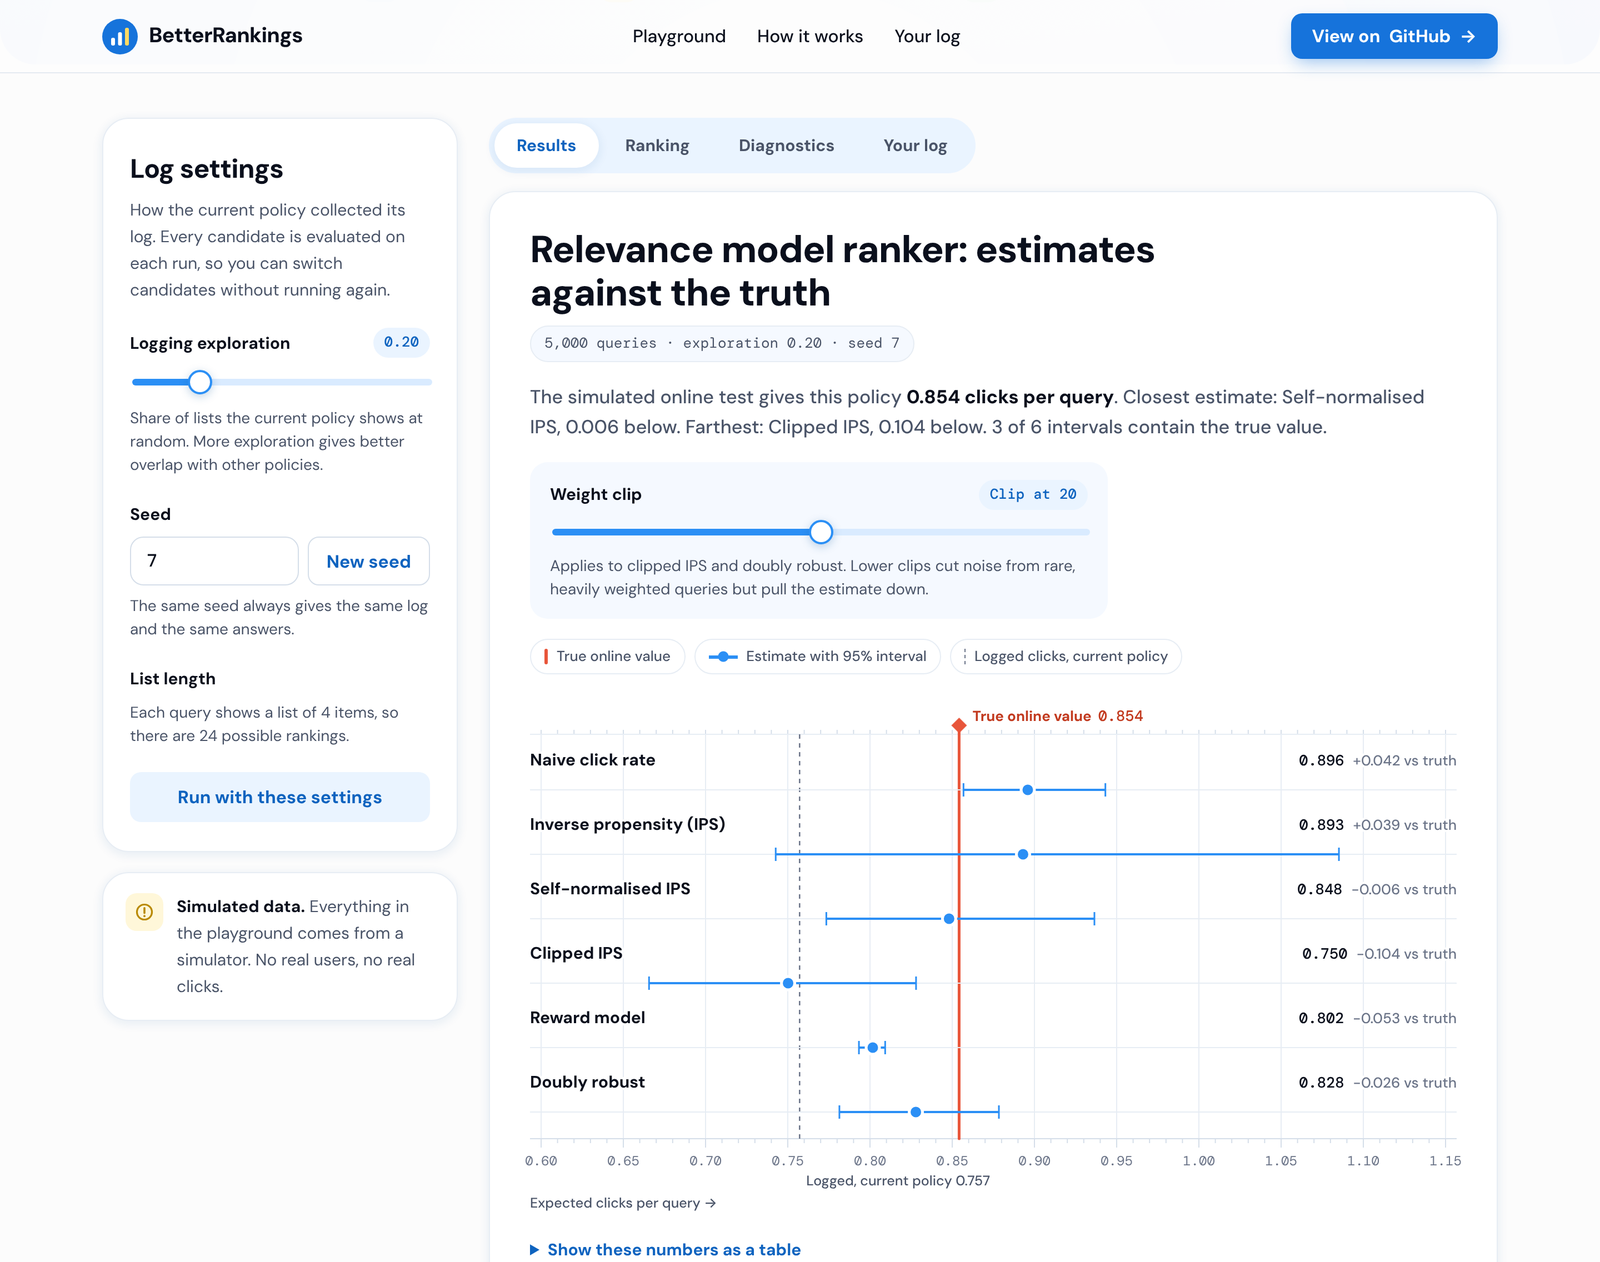
- Doubly robust estimates landed within 2% of the measured click rates.
- 95% confidence intervals covered the truth in 12 of 12 experiments.
- Error was 3× lower than the dataset’s standard benchmark setup.
Fixing the data
Two data-quality problems in the public logs were throwing off the estimates:
- Miscalibrated propensities. The logged probabilities of showing each item didn’t match actual behaviour.
- A 4–5% slate-competition effect. Items shown together compete for clicks.
Re-estimating the propensities and modelling competing items cut error from 4–7% to under 2% in all three campaigns, with intervals 2–3× tighter.
Stack
Python · NumPy · Pandas · SQL